gpt-oss-20b MXFP4 on Strix Halo: Benchmarks
Tested 2026-11-16 on llama.cpp build b12360: gpt-oss-20b MXFP4 generates 70.7 tokens per second and processes a 4096-token prompt at 1616 tokens per second with the Vulkan backend.
Machine and build
| Item | Value |
|---|---|
| Tested | 2026-11-16 |
| Machine | AMD Ryzen AI Max+ 395 (Strix Halo), Radeon 8060S GPU (gfx1151), 128 GB unified memory, Windows |
| GPU driver | AMD proprietary driver 32.0.32015.7029 (2026-10-17), AMD Software 26.20.15.07 |
| GPU memory visible to llama.cpp | Vulkan 111.9 GiB, ROCm 107.9 GiB |
| llama.cpp build | b12360, official release |
| Vulkan binaries | llama-b12360-bin-win-vulkan-x64.zip |
| ROCm binaries | llama-b12360-bin-win-rocm-10.0-x64.zip, with AMD rocm-sdk-libraries 7.14.1 |
Speed and memory
| Measure | Vulkan | ROCm |
|---|---|---|
| Prompt processing, 4096 tokens (tok/s) | 1616 | 1617 |
| Generation, 512 tokens (tok/s) | 70.7 | 61.3 |
| File size (GiB) | 11.28 | same file |
| GPU memory used (GiB) | 12.1 | not measured |
| Load time (s) | 6.6 | not measured |
Speed by context depth
| Context already filled (tokens) | Prompt, 512 tokens (tok/s) | Generation, 128 tokens (tok/s) |
|---|---|---|
| 0 | 1710 | 71.2 |
| 8192 | 1191 | 64.4 |
| 32768 | 633 | 55.7 |
| 8192, q8 KV cache | 1220 | 66.0 |
Server timings
| Task | Prompt tokens | Prompt time (s) | Prompt (tok/s) | Reply tokens | Reply time (s) | Reply (tok/s) |
|---|---|---|---|---|---|---|
| Short chat question | 82 | 0.25 | 331 | 242 | 3.4 | 70.4 |
| 4K-token document summary | 6014 | 3.96 | 1519 | 232 | 3.6 | 64.2 |
| Coding task | 52 | 0.16 | 333 | 512 | 7.7 | 66.7 |
These timings come from llama-server with a 16K context, flash attention on, and temperature 0. "Not recorded" means the run is older than the runner version that saves that value.
Coding test
Each model wrote a falling-block puzzle game as one HTML file. A valid output is a complete HTML document, and you can play it in the card.
A script then checks that each game runs. The script loads the game in headless Chrome, in the same sandboxed frame as this page. The script clicks the game, presses Enter, Space and the arrow keys, and compares screenshots. A game does not run when the browser rejects its script or when the screen never changes. The check records each script error. The check does not change the game file.
Each model got the same prompt (prompt version 1) as its only message, with no system prompt and a budget of 98,304 output tokens shared by thinking and the answer. Thinking was on wherever the model offers it, capped at 32,768 tokens where the model or service accepts a cap. The local models and the other references ran at temperature 0. Claude Opus 4.6 ran at its default temperature, because Bedrock rejects a temperature setting when thinking is on for Claude models.
Each result below has the same layout: a status, the measured numbers, the output (or a failure message in its place) and the raw model output. The cloud services report total time only, so their prompt processing time, generation time and speed show as not reported.
The coding prompt
This is an entry in a contest. A panel of human judges will play your game, compare it with games from other entrants and pick the most impressive one. Make the game as visually impressive and as fun to play as you can: graphics, animation, effects, polish and feel all count. Do not stop at the minimum. The game must also work correctly, and every requirement below must work.

Write a complete falling-block puzzle game, in the style of the game that Alexey Pajitnov created in Moscow in 1984, as one self-contained HTML file.

Requirements:
- A 10 by 20 grid and the 7 standard four-square pieces.
- Pieces fall on their own and speed up as the player clears more lines.
- Left and right arrow keys move the piece. The up arrow key rotates it. The down arrow key moves it down faster. The space bar drops it to the bottom. The P key pauses the game.
- The arrow keys and the space bar must not scroll the page.
- Pieces cannot move through walls, the floor or other pieces.
- A full row clears, and the rows above it move down.
- Show the score, the number of cleared lines and the next piece.
- Before the game starts, show the controls on the page. The game starts when the player clicks the page or presses any key.
- When a new piece cannot enter the grid, show a game over message on the page. The player can start a new game with the Enter key or a click.
- Show every message on the page itself. Do not use alert, confirm or prompt.
- Sound is optional. If the game has sound, it must stay off until the player turns it on.
- Keep all game state in memory. Do not use localStorage, sessionStorage, IndexedDB or cookies.
- The whole page must fit in a frame 800 pixels wide and 640 pixels high.
- Put all CSS and JavaScript inline in the file. Do not load any external scripts, fonts, images or other files, and do not make network requests.
- Do not use the word "Tetris" anywhere in the file.

Reply with only the HTML file.
gpt-oss-20b MXFP4
This model, run 2026-11-09Valid output| Input tokens | 452 |
|---|---|
| Output tokens (thinking and answer) | 35,827 |
| Prompt processing time | 0.4 s |
| Generation time | 10.3 min |
| Generation speed | 57.7 tok/s |
| Total time | 10.3 min |
| Stop reason | stop |
| Output limit and thinking cap | 98,304 tokens, thinking cap 32,768 |
| Temperature | 0 |
| Removed before display | nothing |
Raw model output (126,192 characters)
The full reply as the model returned it, including any reasoning. Open it as a text file.
Loading...
Claude Opus 4.6
Reference: closed model, cloud, generated 2026-11-14Valid output| Input tokens | 519 |
|---|---|
| Output tokens (thinking and answer) | 24,023 |
| Prompt processing time | not reported |
| Generation time | not reported |
| Generation speed | not reported |
| Total time | 4.3 min |
| Stop reason | end_turn |
| Output limit and thinking cap | 98,304 tokens, thinking cap 32,768 |
| Temperature | model default (thinking on) |
| Removed before display | code fence |
Raw model output (33,491 characters)
The full reply as the model returned it, including any reasoning. Open it as a text file.
Loading...
GLM-5
Reference: open-weight model, full size in the cloud, generated 2026-11-13Runs with errors| Input tokens | 451 |
|---|---|
| Output tokens (thinking and answer) | 8,777 |
| Prompt processing time | not reported |
| Generation time | not reported |
| Generation speed | not reported |
| Total time | 89.0 s |
| Stop reason | end_turn |
| Output limit and thinking cap | 98,304 tokens, thinking cap none |
| Temperature | 0 |
| Removed before display | code fence |
Runs with errors: the browser reported a script error, "TypeError: Cannot read properties of undefined (reading '0')". The game still responds to input.
Raw model output (33,812 characters)
The full reply as the model returned it, including any reasoning. Open it as a text file.
Loading...
Drawing test
Each model draws a scene as an SVG image. A valid output is a complete SVG image. gpt-oss-20b MXFP4 does not accept images, so it skips the second part of the test, where a vision model judges the drawings.
The scene is a nod to soviet.recipes, my project of classic Soviet recipes with modern instructions. A hungry man staring at a dumpling on his monitor is roughly what working on that project looks like.
Each model got the same prompt (prompt version 1) as its only message, with no system prompt and a budget of 98,304 output tokens shared by thinking and the answer. Thinking was on wherever the model offers it, capped at 32,768 tokens where the model or service accepts a cap. The local models and the other references ran at temperature 0. Claude Opus 4.6 ran at its default temperature, because Bedrock rejects a temperature setting when thinking is on for Claude models.
Each result below has the same layout: a status, the measured numbers, the output (or a failure message in its place) and the raw model output. The cloud services report total time only, so their prompt processing time, generation time and speed show as not reported.
The drawing prompt
This is an entry in a contest. A panel of human judges will compare your image with images from other entrants and pick the most impressive one. Make the image as visually impressive as you can: composition, detail, color, lighting, character and charm all count. Do not stop at the minimum.

The scene:
- A Soviet-looking man sits at a desk in his study.
- On the desk is a computer with a monitor.
- The monitor shows an image of a single pelmen (one small crescent-shaped dumpling).
- The man looks hungry: he licks his lips as he looks at the pelmen on the screen.

Technical requirements:
- Write one SVG image with a viewBox of 0 0 800 600.
- You can use any SVG shapes, paths, text, gradients, patterns and filters. You can animate with SMIL or CSS inside the SVG.
- Do not use scripts, embedded images, foreignObject or external resources such as fonts or links.
- The SVG must be valid XML and must display correctly in a web browser.

Reply with only the SVG code.
gpt-oss-20b MXFP4
This model, run 2026-11-09Valid output| Input tokens | 291 |
|---|---|
| Output tokens (thinking and answer) | 26,997 |
| Prompt processing time | 0.4 s |
| Generation time | 7.6 min |
| Generation speed | 59.2 tok/s |
| Total time | 7.6 min |
| Stop reason | stop |
| Output limit and thinking cap | 98,304 tokens, thinking cap 32,768 |
| Temperature | 0 |
| Removed before display | nothing |
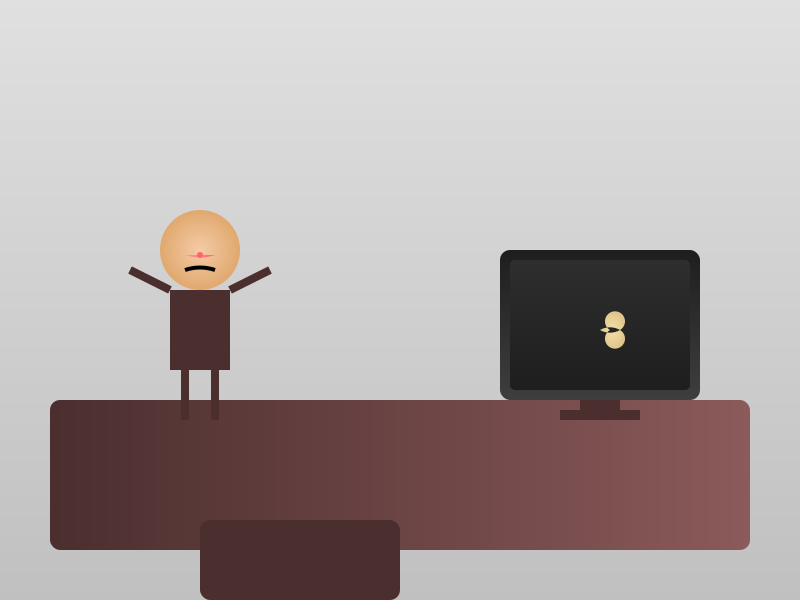
Raw model output (112,582 characters)
The full reply as the model returned it, including any reasoning. Open it as a text file.
Loading...
Claude Opus 4.6
Reference: closed model, cloud, generated 2026-11-14Valid output| Input tokens | 282 |
|---|---|
| Output tokens (thinking and answer) | 28,581 |
| Prompt processing time | not reported |
| Generation time | not reported |
| Generation speed | not reported |
| Total time | 4.2 min |
| Stop reason | end_turn |
| Output limit and thinking cap | 98,304 tokens, thinking cap 32,768 |
| Temperature | model default (thinking on) |
| Removed before display | code fence |
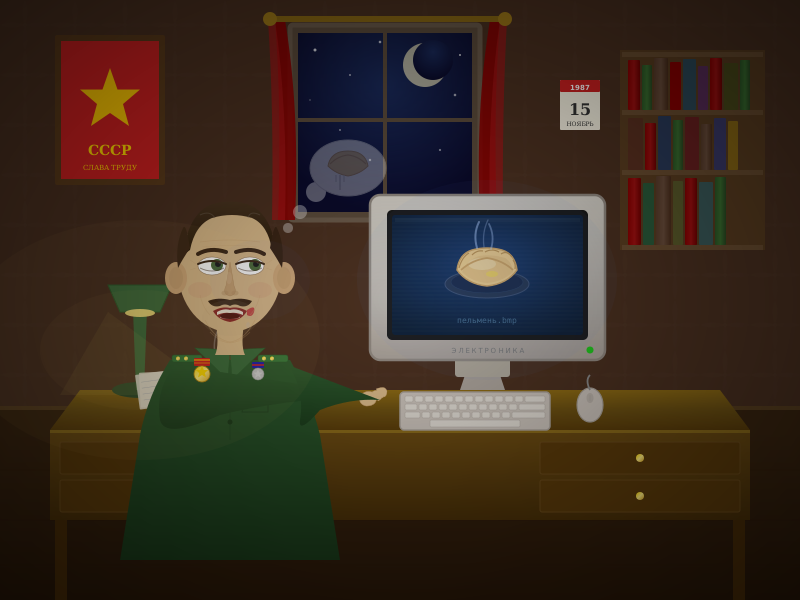
Raw model output (36,803 characters)
The full reply as the model returned it, including any reasoning. Open it as a text file.
Loading...
GLM-5
Reference: open-weight model, full size in the cloud, generated 2026-11-13Valid output| Input tokens | 229 |
|---|---|
| Output tokens (thinking and answer) | 7,295 |
| Prompt processing time | not reported |
| Generation time | not reported |
| Generation speed | not reported |
| Total time | 58.0 s |
| Stop reason | end_turn |
| Output limit and thinking cap | 98,304 tokens, thinking cap none |
| Temperature | 0 |
| Removed before display | code fence |
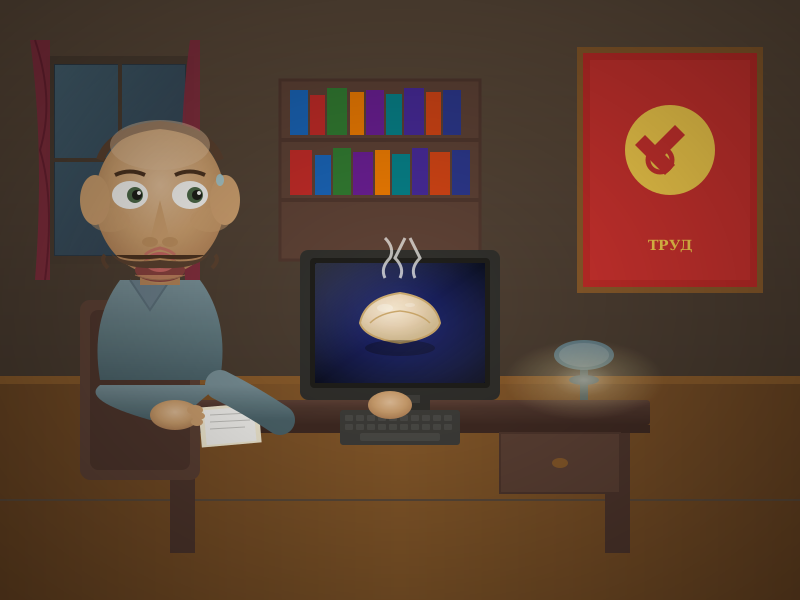
Raw model output (20,588 characters)
The full reply as the model returned it, including any reasoning. Open it as a text file.
Loading...
Test setup
The tests, flags and memory measurement are in How to Benchmark a Local LLM on Strix Halo.