Mage-VL-Cowork Q8_0 on Strix Halo: Benchmarks
Tested 2026-11-13 to 2026-11-14 on llama.cpp build b12360: Mage-VL-Cowork Q8_0 generates 47.7 tokens per second and processes a 4096-token prompt at 1504 tokens per second with the Vulkan backend.
Machine and build
| Item | Value |
|---|---|
| Tested | 2026-11-13 to 2026-11-14 |
| Machine | AMD Ryzen AI Max+ 395 (Strix Halo), Radeon 8060S GPU (gfx1151), 128 GB unified memory, Windows |
| GPU driver | AMD proprietary driver 32.0.32015.7029 (2026-10-17), AMD Software 26.20.15.07 |
| GPU memory visible to llama.cpp | Vulkan 111.9 GiB, ROCm 107.9 GiB |
| llama.cpp build | b12360, official release |
| Vulkan binaries | llama-b12360-bin-win-vulkan-x64.zip |
| ROCm binaries | llama-b12360-bin-win-rocm-10.0-x64.zip, with AMD rocm-sdk-libraries 7.14.1 |
Speed and memory
| Measure | Vulkan | ROCm |
|---|---|---|
| Prompt processing, 4096 tokens (tok/s) | 1504 | 1912 |
| Generation, 512 tokens (tok/s) | 47.7 | 42.8 |
| File size (GiB) | 4.37 | same file |
| GPU memory used (GiB) | 6.7 | not measured |
| Load time (s) | 4.6 | not measured |
Speed by context depth
| Context already filled (tokens) | Prompt, 512 tokens (tok/s) | Generation, 128 tokens (tok/s) |
|---|---|---|
| 0 | 1894 | 48.3 |
| 8192 | 831 | 37.0 |
| 32768 | 323 | 22.8 |
| 8192, q8 KV cache | 804 | 39.2 |
Server timings
| Task | Prompt tokens | Prompt time (s) | Prompt (tok/s) | Reply tokens | Reply time (s) | Reply (tok/s) |
|---|---|---|---|---|---|---|
| Short chat question | not recorded | 0.11 | 242 | not recorded | not recorded | 46.5 |
| 4K-token document summary | not recorded | 5.10 | 1297 | not recorded | not recorded | 37.1 |
| Coding task | not recorded | 0.06 | 994 | not recorded | not recorded | 45.3 |
These timings come from llama-server with a 16K context, flash attention on, and temperature 0. "Not recorded" means the run is older than the runner version that saves that value.
Coding test
Each model wrote a falling-block puzzle game as one HTML file. A valid output is a complete HTML document, and you can play it in the card.
Each model got the same prompt (prompt version 1) as its only message, with no system prompt and a budget of 98,304 output tokens shared by thinking and the answer. Thinking was on wherever the model offers it, capped at 32,768 tokens where the model or service accepts a cap. The local models and the other references ran at temperature 0. Claude Opus 4.6 ran at its default temperature, because Bedrock rejects a temperature setting when thinking is on for Claude models.
Each result below has the same layout: a status, the measured numbers, the output (or a failure message in its place) and the raw model output. The cloud services report total time only, so their prompt processing time, generation time and speed show as not reported.
The coding prompt
This is an entry in a contest. A panel of human judges will play your game, compare it with games from other entrants and pick the most impressive one. Make the game as visually impressive and as fun to play as you can: graphics, animation, effects, polish and feel all count. Do not stop at the minimum. The game must also work correctly, and every requirement below must work.

Write a complete falling-block puzzle game, in the style of the game that Alexey Pajitnov created in Moscow in 1984, as one self-contained HTML file.

Requirements:
- A 10 by 20 grid and the 7 standard four-square pieces.
- Pieces fall on their own and speed up as the player clears more lines.
- Left and right arrow keys move the piece. The up arrow key rotates it. The down arrow key moves it down faster. The space bar drops it to the bottom. The P key pauses the game.
- The arrow keys and the space bar must not scroll the page.
- Pieces cannot move through walls, the floor or other pieces.
- A full row clears, and the rows above it move down.
- Show the score, the number of cleared lines and the next piece.
- Before the game starts, show the controls on the page. The game starts when the player clicks the page or presses any key.
- When a new piece cannot enter the grid, show a game over message on the page. The player can start a new game with the Enter key or a click.
- Show every message on the page itself. Do not use alert, confirm or prompt.
- Sound is optional. If the game has sound, it must stay off until the player turns it on.
- Keep all game state in memory. Do not use localStorage, sessionStorage, IndexedDB or cookies.
- The whole page must fit in a frame 800 pixels wide and 640 pixels high.
- Put all CSS and JavaScript inline in the file. Do not load any external scripts, fonts, images or other files, and do not make network requests.
- Do not use the word "Tetris" anywhere in the file.

Reply with only the HTML file.
Mage-VL-Cowork Q8_0
This model, run 2026-11-09No valid output| Input tokens | 463 |
|---|---|
| Output tokens (thinking and answer) | 53,096 |
| Prompt processing time | 0.3 s |
| Generation time | 36.1 min |
| Generation speed | 24.5 tok/s |
| Total time | 36.1 min |
| Stop reason | stop |
| Output limit and thinking cap | 98,304 tokens, thinking cap 32,768 |
| Temperature | 0 |
| Removed before display | reasoning block, text outside the code |
Failed: The reply contains no complete HTML file. The raw output below shows what the model wrote.
Raw model output (266,885 characters)
The full reply as the model returned it, including any reasoning. Open it as a text file.
Loading...
Claude Opus 4.6
Reference: closed model, cloud, generated 2026-11-14Valid output| Input tokens | 519 |
|---|---|
| Output tokens (thinking and answer) | 24,023 |
| Prompt processing time | not reported |
| Generation time | not reported |
| Generation speed | not reported |
| Total time | 4.3 min |
| Stop reason | end_turn |
| Output limit and thinking cap | 98,304 tokens, thinking cap 32,768 |
| Temperature | model default (thinking on) |
| Removed before display | code fence |
Raw model output (33,491 characters)
The full reply as the model returned it, including any reasoning. Open it as a text file.
Loading...
GLM-5
Reference: open-weight model, full size in the cloud, generated 2026-11-13Valid output| Input tokens | 451 |
|---|---|
| Output tokens (thinking and answer) | 8,777 |
| Prompt processing time | not reported |
| Generation time | not reported |
| Generation speed | not reported |
| Total time | 89.0 s |
| Stop reason | end_turn |
| Output limit and thinking cap | 98,304 tokens, thinking cap none |
| Temperature | 0 |
| Removed before display | code fence |
Raw model output (33,812 characters)
The full reply as the model returned it, including any reasoning. Open it as a text file.
Loading...
Vision language model test
This test has two parts. In the first part, each model draws a scene as an SVG image. A valid output is a complete SVG image. In the second part, the model under test looks at each drawing, without being told which model drew it, and marks each criterion YES or NO. Only models that accept images take the second part.
Drawing
The scene is a nod to soviet.recipes, my project of classic Soviet recipes with modern instructions. A hungry man staring at a dumpling on his monitor is roughly what working on that project looks like.
Each model got the same prompt (prompt version 1) as its only message, with no system prompt and a budget of 98,304 output tokens shared by thinking and the answer. Thinking was on wherever the model offers it, capped at 32,768 tokens where the model or service accepts a cap. The local models and the other references ran at temperature 0. Claude Opus 4.6 ran at its default temperature, because Bedrock rejects a temperature setting when thinking is on for Claude models.
Each result below has the same layout: a status, the measured numbers, the output (or a failure message in its place) and the raw model output. The cloud services report total time only, so their prompt processing time, generation time and speed show as not reported.
The drawing prompt
This is an entry in a contest. A panel of human judges will compare your image with images from other entrants and pick the most impressive one. Make the image as visually impressive as you can: composition, detail, color, lighting, character and charm all count. Do not stop at the minimum.

The scene:
- A Soviet-looking man sits at a desk in his study.
- On the desk is a computer with a monitor.
- The monitor shows an image of a single pelmen (one small crescent-shaped dumpling).
- The man looks hungry: he licks his lips as he looks at the pelmen on the screen.

Technical requirements:
- Write one SVG image with a viewBox of 0 0 800 600.
- You can use any SVG shapes, paths, text, gradients, patterns and filters. You can animate with SMIL or CSS inside the SVG.
- Do not use scripts, embedded images, foreignObject or external resources such as fonts or links.
- The SVG must be valid XML and must display correctly in a web browser.

Reply with only the SVG code.
Mage-VL-Cowork Q8_0
This model, run 2026-11-09No valid output| Input tokens | 238 |
|---|---|
| Output tokens (thinking and answer) | 98,304 |
| Prompt processing time | 0.2 s |
| Generation time | 93.3 min |
| Generation speed | 17.6 tok/s |
| Total time | 93.3 min |
| Stop reason | length (hit the output limit) |
| Output limit and thinking cap | 98,304 tokens, thinking cap 32,768 |
| Temperature | 0 |
| Removed before display | reasoning block, text outside the code |
Failed: The reply contains no complete SVG image. The model stopped at the 98,304-token output limit. The raw output below shows what the model wrote.
Raw model output (476,426 characters)
The full reply as the model returned it, including any reasoning. Open it as a text file.
Loading...
Claude Opus 4.6
Reference: closed model, cloud, generated 2026-11-14Valid output| Input tokens | 282 |
|---|---|
| Output tokens (thinking and answer) | 28,581 |
| Prompt processing time | not reported |
| Generation time | not reported |
| Generation speed | not reported |
| Total time | 4.2 min |
| Stop reason | end_turn |
| Output limit and thinking cap | 98,304 tokens, thinking cap 32,768 |
| Temperature | model default (thinking on) |
| Removed before display | code fence |
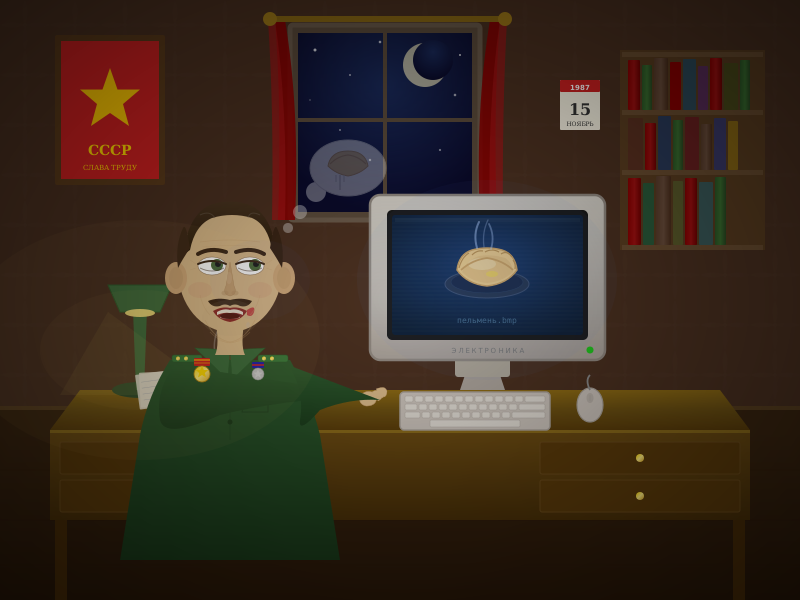
Raw model output (36,803 characters)
The full reply as the model returned it, including any reasoning. Open it as a text file.
Loading...
GLM-5
Reference: open-weight model, full size in the cloud, generated 2026-11-13Valid output| Input tokens | 229 |
|---|---|
| Output tokens (thinking and answer) | 7,295 |
| Prompt processing time | not reported |
| Generation time | not reported |
| Generation speed | not reported |
| Total time | 58.0 s |
| Stop reason | end_turn |
| Output limit and thinking cap | 98,304 tokens, thinking cap none |
| Temperature | 0 |
| Removed before display | code fence |
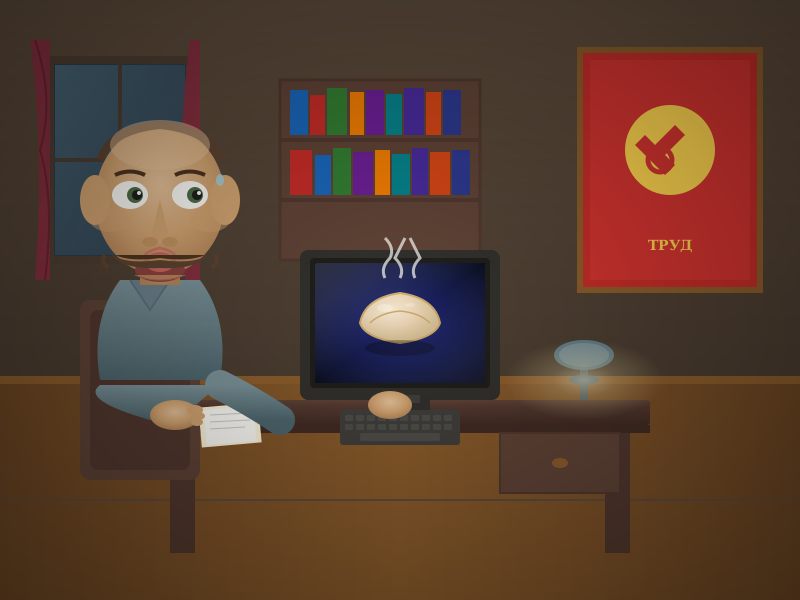
Raw model output (20,588 characters)
The full reply as the model returned it, including any reasoning. Open it as a text file.
Loading...
Judging the drawings
The judge saw each drawing as an 800 by 600 PNG, one image per request. A valid output is exactly 8 YES/NO lines and one JUDGEMENT line, as the prompt asks. Up to 98,304 output tokens per answer, temperature 0, thinking capped at 32,768 tokens.
The judging prompt
You are a judge in a drawing contest. Look at the attached image. The artist was asked to draw this scene:

- A Soviet-looking man sits at a desk in his study.
- On the desk is a computer with a monitor.
- The monitor shows an image of a single pelmen (one small crescent-shaped dumpling).
- The man looks hungry: he licks his lips as he looks at the pelmen on the screen.

For each criterion below, decide whether the image clearly shows it.

Criteria:
1. The man looks Soviet.
2. The man sits at a desk.
3. The room is a study.
4. A computer with a monitor is on the desk.
5. The monitor shows a single pelmen.
6. The pelmen is a small crescent-shaped dumpling.
7. The man licks his lips.
8. The man looks at the pelmen on the screen.

Reply in exactly this format, with no other text:
1. YES or NO
2. YES or NO
3. YES or NO
4. YES or NO
5. YES or NO
6. YES or NO
7. YES or NO
8. YES or NO
JUDGEMENT: two to four sentences about how well the image matches the scene and how visually impressive it is.
Mage-VL-Cowork Q8_0 judges the drawing by Mage-VL-Cowork Q8_0
Judge: this model, run 2026-11-09Not run| Input tokens | - |
|---|---|
| Output tokens (thinking and answer) | - |
| Prompt processing time | - |
| Generation time | - |
| Generation speed | - |
| Total time | - |
| Stop reason | - |
| Output limit and thinking cap | - |
| Temperature | - |
| Removed before display | - |
Not run: there is no valid drawing by Mage-VL-Cowork Q8_0 to judge.
Raw model output: none, because this test has not run.
Mage-VL-Cowork Q8_0 judges the drawing by Claude Opus 4.6
Judge: this model, run 2026-11-09No valid output| Input tokens | 757 |
|---|---|
| Output tokens (thinking and answer) | 494 |
| Prompt processing time | 0.7 s |
| Generation time | 11.2 s |
| Generation speed | 44.0 tok/s |
| Total time | 12.0 s |
| Stop reason | stop |
| Output limit and thinking cap | 98,304 tokens, thinking cap 32,768 |
| Temperature | 0 |
| Removed before display | reasoning block |
Failed: the reply is not in the requested format. The raw output below shows what the model wrote.
Raw model output (2,405 characters)
The full reply as the model returned it, including any reasoning. Open it as a text file.
Loading...
Mage-VL-Cowork Q8_0 judges the drawing by GLM-5
Judge: this model, run 2026-11-09No valid output| Input tokens | 483 |
|---|---|
| Output tokens (thinking and answer) | 1,523 |
| Prompt processing time | 0.6 s |
| Generation time | 35.4 s |
| Generation speed | 43.0 tok/s |
| Total time | 36.0 s |
| Stop reason | stop |
| Output limit and thinking cap | 98,304 tokens, thinking cap 32,768 |
| Temperature | 0 |
| Removed before display | reasoning block |
Failed: the reply is empty. The raw output below shows everything the model returned, including its reasoning.
Raw model output (6,707 characters)
The full reply as the model returned it, including any reasoning. Open it as a text file.
Loading...
Test setup
The tests, flags and memory measurement are in How to Benchmark a Local LLM on Strix Halo.